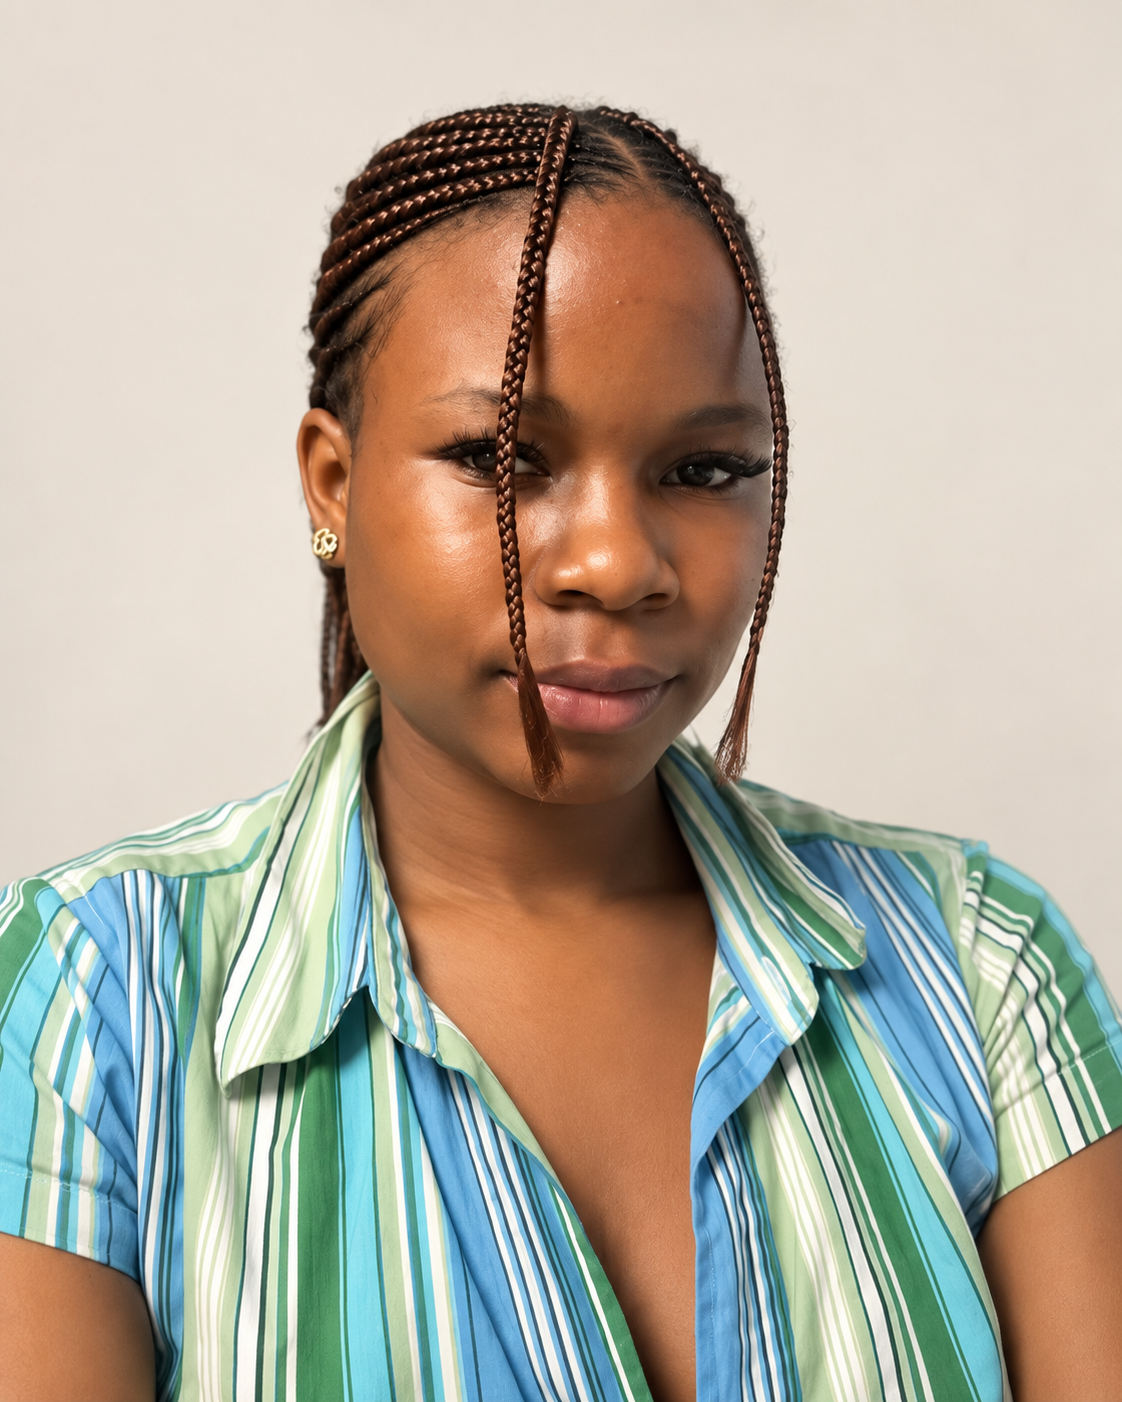
I’m Fadekemi Fadare, an AI engineer. I work on AI safety, evaluation, and integration: understanding where a system falls short, building safeguards around those failures, and connecting models to the tools, data, and workflows they need to be useful.
Much of my work starts with questions about reliability. Is an answer supported by evidence? Does a model follow the intended scope? Can an agent complete a multi-step task consistently? And when a conversation becomes more serious, does the system recognise that its response needs to change? I build evaluation workflows that make these questions testable, then use what they reveal to improve the system.
I design and build AI systems that combine language models, retrieval, and agentic reasoning to solve real product problems. My work includes selecting and fine-tuning models, designing RAG pipelines, orchestrating multi-agent workflows, and integrating voice capabilities. I use structured outputs, evaluation, and safety checks to make these systems more reliable in practice. I’ve built health companions at SRHIN, designed the AI architecture for Techcori’s career and recruitment platform, and improved model reliability and agent coordination at Budi Digital Labs.
Health AI is a recurring thread in my work. My clinical and community-health experience shapes how I approach sensitive information, clear boundaries, and escalation. Through SafeBench, I’m exploring when maternal-health conversations should trigger a stronger safety response. Through GUIDE-REG, I’m investigating how changes in clinical guidelines can guide targeted regression tests for clinical AI. Both are ongoing research projects.
My academic background is in Human Nutrition and Dietetics: I graduated from Osun State University with a Second Class Upper and trained across clinical units at OAUTHC and community health services in Osun State. I’m now studying for an MSc in Financial Engineering at WorldQuant University. I’ve also completed DataCamp certifications in data analysis, data science, and AI engineering, with a postgraduate diploma in computer science in view.
PORTFOLIO
My work.
Products, tools, and research projects I’ve worked on. The problem, what I built to address it, and where to find it.
01
Budi Digital Labs · Fintech
MyBudi
Problem
The existing budgeting and money-coaching app needed more reliable model responses and coordination across multi-step tasks, along with support for voice interaction.
Solution
Evaluated production models, improved multi-agent coordination, and added voice capabilities to a budgeting and money-coaching app.
Maternal-health questions require grounded information. A chatbot that generates answers without retrieving supporting evidence can produce inaccurate or hallucinated medical information.
Solution
Built a maternal-health chatbot with hybrid retrieval using Supabase and Tavily, available on WhatsApp and the web. Project evaluation: 92.4% retrieval precision and 55% fewer hallucinations than non-RAG baselines.
A perinatal mental-health companion needs to recognise crisis signals and apply safeguards while supporting conversations across Nigerian languages.
Solution
Developed a conversational support system with crisis detection across five Nigerian languages. Project evaluation recorded 100% sensitivity and 98.3% specificity. Crisis-safeguard work accepted for international conference presentation.
A career and recruitment platform needed an AI foundation to turn retrieved and enriched information into structured classifications and scores that could be used in its product.
Solution
As founding AI engineer, built the AI architecture and pipelines for retrieval, enrichment, classification, and scoring. Used GPT-4o function calling and Supabase pgvector with streaming to an analytics dashboard.
Forecasting infectious-disease outbreaks requires accounting for seasonal patterns, expressing uncertainty, and testing whether predictions hold up across different years.
Solution
Built a forecasting system for cholera, Lassa fever, mpox, and dengue across African settings. Used seasonal modelling, Wilson confidence intervals, and leave-one-year-out validation; deployed with FastAPI on Railway.
Midwives need a way to identify mothers who may require further mental-health assessment or support during routine perinatal care.
Solution
Built a web application for midwives to screen for perinatal mental-health concerns and identify mothers who may need further assessment or support during routine care.
Vaccination follow-through involves keeping track of schedules, finding nearby primary health centres, and reaching people with reminders through accessible channels.
Solution
Built a scheduling agent with location-based primary-health-centre recommendations and reminders through WhatsApp, Gmail, and SMS, for use across primary health centres in Oyo State.
Underserved communities in Oyo State need an accessible pathway to family-planning information and support within the BetaMama Pikin ecosystem.
Solution
Developed a WhatsApp-based family-planning information and support pathway within the BetaMama Pikin ecosystem for underserved communities in Oyo State.
Conference Abstract · Co-Author · Clinical AI Showcase
Omidan
Oxford Clinical AI for Healthcare Leaders Conference 2026 Somerville College, Oxford, United Kingdom · June 25, 2026
An AI-powered clinical decision support platform embedding maternal mental health screening into routine antenatal care for Nigerian frontline providers.
Session Type: Virtual Lightning Talk · Main Presenter: Fadekemi Fadare
ONGOING RESEARCH
In progress.
Research questions I’m working on.
Clinical AI · In progress
GUIDE-REG
Change-impact analysis and targeted regression testing for clinical AI under evolving guidelines.
Problem
Clinical guidelines change, and those updates can affect which decisions an AI system should make for particular patients. The research question is how to identify the affected decisions and test them without rerunning every possible case.
Research approach
I’m working on a framework that traces changes between guideline versions into structured rules and clinical dependencies, identifies affected patient states, and generates targeted regression tests. The study is designed to compare this approach with broader regression testing, incorporating clinician validation.
Conversational AI safety · In progress
SafeBench
Evaluating escalation lag in maternal-health conversations.
Problem
A chatbot can produce reasonable individual answers yet miss the point at which new information calls for a stronger safety response. Aggregate scores can hide these failures across a conversation.
Research approach
I’m developing a benchmark and mitigation framework to measure escalation lag in maternal-health conversational AI. The work focuses on structured evaluation of multi-turn conversations and identifying when the system should change its response as the situation evolves.
BEYOND THE WORK
Off the clock.
Music I return to, places I’ve been, and books on my shelf.